10 Strategies for Reducing Costs and Context
Token Efficiency in AI Coding Assistants
11.08.2026
Senior Data Scientist
Introduction
AI coding assistants can search repositories, modify multiple files, run tests, and respond to errors. However, this capability comes with a less visible resource: the model context, which is processed at every step. The longer a session runs, the more files, command outputs, tool definitions, and previous messages can be fed back into the model. As a result, a seemingly small coding task can become costly, slow, and increasingly difficult for the assistant to process.
Token efficiency, therefore, does not simply mean writing shorter prompts. Rather, it involves providing an assistant with the smallest possible sufficient context for the decision at hand, while still retaining all the information necessary for a correct and verifiable result.
The implications are no longer merely theoretical. By April 2026—just four months into the year—Uber had already exhausted its entire annual AI budget after the rollout of Claude Code expanded to approximately 5,000 developers faster than financial models had anticipated. The monthly cost per developer averaged $150–$250, while power users reached peak costs of $500–$2,000 (Janakiram, 2026). Amazon reported a similar pattern: an internal Claude Sonnet implementation for matching product listings cost $1.8 million, which was 860% over the original budget. The cost overrun went unnoticed for nearly five months. Two other internal projects separately exceeded their budgets by $541,000 and $134,000, respectively (Udinmwen, 2026). Both cases share the same root cause: token-based, agent-driven coding tools do not behave like software with a flat-rate license fee. Unchecked context growth can therefore turn everyday development work into a spiraling bill before anyone notices.
This article outlines practical measures for developers and platform teams, drawing primarily on the official recommendations from GitHub Copilot and Claude Code. In addition, it evaluates a growing ecosystem of tools for repository indexing, selective querying, output compression, and compact data representation.
What consumes tokens in an AI coding workflow?
A model request can contain significantly more than just the developer's last instruction. Depending on the assistant, this may include the conversation history, selected source files, repository instructions, tool definitions, terminal output, diffs, test results, retrieved documentation, as well as previous plans or results from the assistant. Generated code and explanations also produce output tokens.
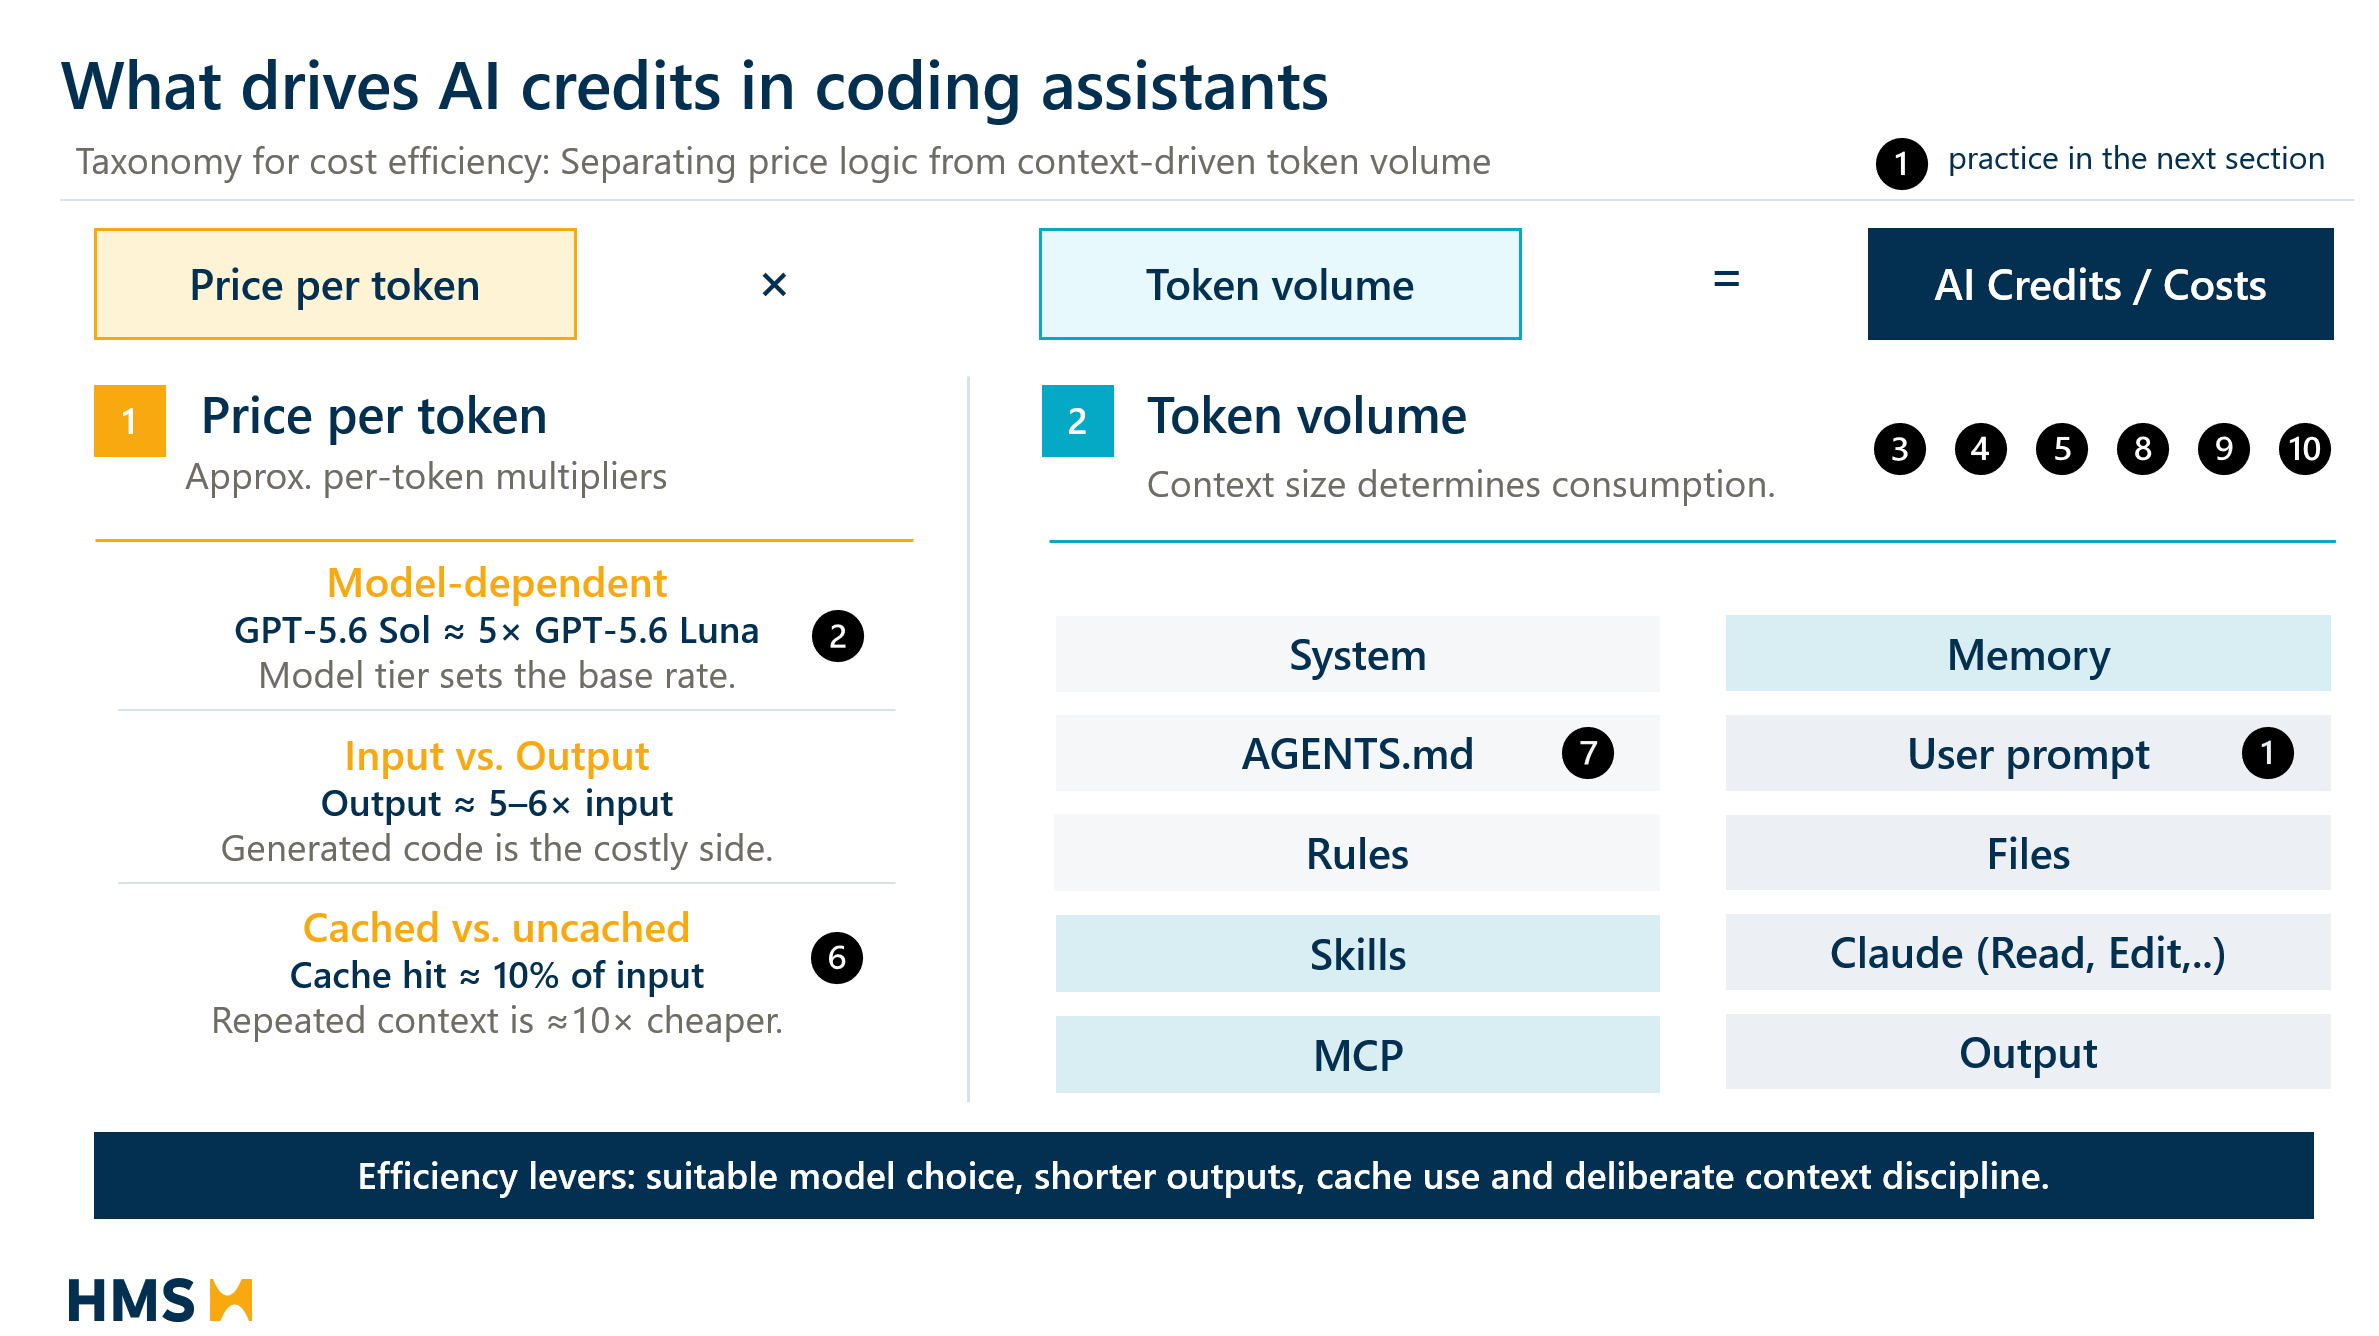
Coding workloads are particularly context-intensive because agents frequently repeat a cycle of planning, searching, reading, editing, testing, and correcting. Each step can add new information or reintroduce existing context. Large files, detailed logs, broad repository scans, and unsuccessful attempts can quickly crowd out much of the information that is actually relevant in a single session.
The goal, therefore, is not to minimize tokens at any cost. Too little context can lead to erroneous changes, overlooked dependencies, and additional correction cycles.
Rather, the relevant optimization metric is:
tokens per successfully completed and validated task.
Ten Measures with the Greatest Impact
The following measures are sorted by their level of impact. The first items influence nearly every step of an agent session and are therefore beneficial for almost every task. The last measures are more situation-specific adjustments that become useful once the fundamental principles have been implemented.
1. Write precise and clearly defined prompts
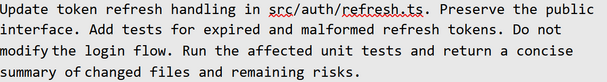
A vague prompt often leads to a broad search and repeated attempts at interpretation. A better prompt defines the goal, boundaries, acceptance criteria, and relevant starting points.
Avoid vague prompts and those without clear boundaries:

Prefer—goals, boundaries, and acceptance criteria:
The same principle applies when troubleshooting a failed test.
Avoid—no starting point and no scope:

Prefer—specify the error, scope, and verification:
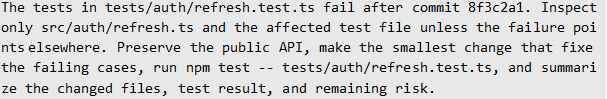
Although this prompt is longer, it reduces overall effort by preventing unnecessary exploration and corrections. By achieving a correct result with fewer interactions, it also shortens the time it takes to implement a working fix.
Include only information that actually changes the assistant’s decisions. Prefer file paths, symbols, failing tests, diffs, and exact error messages over a long description.
2. Adapt the model and the reasoning effort to the task
Using the most powerful reasoning model for every query is rarely cost-effective. GitHub recommends reasoning models for architectural decisions, complex debugging, and system design. Mid-range models are suitable for implementing a clear plan, while lighter models can be used for routine refactoring, formatting, or documentation.
GitHub Copilot’s automatic model selection can also route requests according to their requirements and prevent model switching during a cacheable task.
A practical team guideline might look like this:
- Lightweight model:
Formatting, renaming, boilerplate, documentation, and simple tests - General-purpose model:
Scoped feature implementation, familiar refactorings, and routine debugging - Reasoning model:
Architecture decisions, unknown error patterns, cross-system changes, and security-critical analyses
However, model size is only one factor. The setting for reasoningeffort can be just as important. It determines how much computational power a model expends during inference before it returns its answer.
Coding tools often use a medium setting by default, while published benchmarks may use high settings such as “high,” “xhigh,” or “max.” A model that appears underperforming at a medium reasoning effort can therefore become significantly more powerful if it is allowed to think about a task for longer—and in some cases at a lower inference cost than switching to a larger model.
The values and index scores discussed here are based on Artificial Analysis’s Coding Agents Leaderboard.
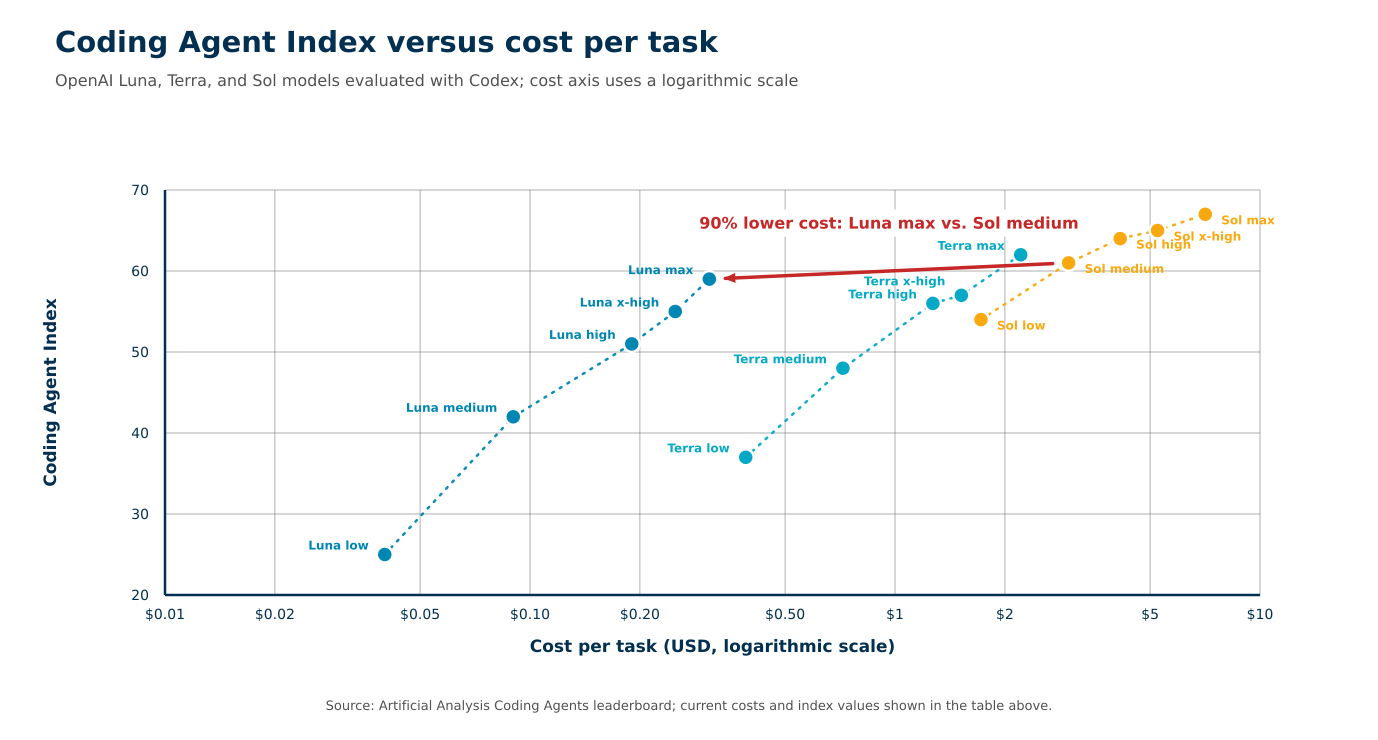
In the GPT-5.6 family, for example, a higher reasoning level of the lightweight Luna model can deliver a near-leading result at significantly lower cost than switching directly to the larger Sol model with its default medium reasoning level.
GPT-5.6 Luna with maximum reasoning achieves an index score of 59 in the benchmark shown, at an estimated cost of $0.31 per task. That’s just two points below GPT-5.6 Sol with medium reasoning ($2.99), while the estimated cost per task drops by about 90%. Luna with x-high reasoning costs $0.25—about 92% less than Sol with medium reasoning—but achieves an index score that is six points lower. For many tasks, the smaller model with higher reasoning effort is therefore the more economical choice, provided that performance close to the top range is sufficient.
However, this cost savings comes at the expense of processing time: In the same benchmark, the average agent time per task increases from about 5.2 minutes for Sol with medium reasoning to about 8 minutes for Luna with maximum reasoning. If a developer has to wait for the result, these additional 2.8 minutes per task may be more important than the lower costs.
Before switching to a larger model, test the lightweight model with high or maximum reasoning on representative tasks.
When doing so, compare not only benchmark scores, but also:
- Cost per successfully completed task
- Latency
- Number of correction loops
Set the reasoning level before starting the session so that prompt caching is not affected.
| Configuration | Coding Agent Index | Cost per task | Savings Compared to Sol (Average) | Score Difference Compared to Sol (Medium) |
|---|---|---|---|---|
| GPT-5.6 Luna (low) | 25 | $0.04 | 99% | −36 points (−59%) |
| GPT-5.6 Luna (medium) | 42 | $0.09 | 97% | −19 points (−31%) |
| GPT-5.6 Luna (high) | 51 | $0.19 | 94% | −10 points (−16%) |
| GPT-5.6 Luna (x-high) | 55 | $0.25 | 92% | −6 points (−10%) |
| GPT-5.6 Luna (max) | 59 | $0.31 | 90% | −2 points (−3%) |
| GPT-5.6 Terra (low) | 37 | $0.39 | 87% | −24 points (−39%) |
| GPT-5.6 Terra (medium) | 48 | $0.72 | 76% | −13 points (−21%) |
| GPT-5.6 Terra (high) | 56 | $1.27 | 58% | −5 points (−8 %) |
| GPT-5.6 Terra (x-high) | 57 | $1.52 | 49% | −4 points (−7%) |
| GPT-5.6 Terra (max) | 62 | $2.21 | 26% | +1 point (+2%) |
| GPT-5.6 Sol (low) | 54 | $1.72 | 42% | −7 points (−11 %) |
| GPT-5.6 Sol (medium) | 61 | $2.99 | Base value | Base value |
| GPT-5.6 Sol (high) | 64 | $4.14 | −38% | +3 points (+5%) |
| GPT-5.6 Sol (x-high) | 65 | $5.24 | −75% | +4 points (+7%) |
| GPT-5.6 Sol (max) | 67 | $7.08 | −137% | +6 points (+10%) |
Note on Interpretation: The percentages were calculated from the benchmark values shown and rounded to whole percentages. Benchmark results depend on the agent harness, task set, reasoning level, and the underlying prices. Before defining an enterprise-wide standard, the selection should be validated against your own repository and workloads.
3. Separation of Planning and Execution
When tackling complex tasks, resist the temptation to conduct research, planning, and implementation all in a single, continuous session. GitHub recommends dividing the work into clearly distinct phases: Use a powerful reasoning model to analyze the codebase and create a concise, verifiable plan, have a developer approve or adapt this plan, and then implement it using a more cost-effective model—ideally in a new session that begins with the approved plan rather than the full planning history.
The main reason for dividing these phases is that research and planning are inherently context-intensive. Examining a repository introduces files, search results, discarded options, and dead ends into the context, and each of these tokens is re-transmitted with every subsequent turn as implementation continues in the same conversation. Starting implementation in a new session discards this accumulated context and reintroduces only the finalized plan. As a result, the implementation model operates with the smallest sufficient context rather than with a record of how the plan was developed.
A leaner context also leads to more reliable implementation. When exploratory planning no longer competes for the model’s attention, the agent is far less likely to revisit outdated considerations, resume an approach already discarded by the plan, or deviate from the agreed-upon scope; each phase works only with what it needs to make the next correct decision. This approach therefore offers three mutually reinforcing advantages:
- Resource-intensive reasoning is used only where it adds value, while execution runs on a more cost-effective model.
- The execution agent receives a smaller, carefully curated context package and thus implements the plan more precisely.
- Human review takes place before extensive changes to the repository result in additional token consumption.
Although starting a new session for implementation clears the prompt cache from the planning session, in practice the resulting costs are rarely significant: Switching from a reasoning model to a more cost-effective execution model would invalidate this cache anyway (see Practice 6), and the small, stable plan quickly builds up a new cache that is reused throughout the many turns of the implementation.
4. Use deterministic workflows whenever possible
AI agents operate probabilistically: The same instruction can lead to different plans and results, and small errors can compound in a multi-step workflow.
Therefore, you should not assign the model a task that can be reliably handled by an existing deterministic tool.
Recurring operations such as:
- Running a test suite
- Formatting
- Linting
- Scanning dependencies
- Retrieving AWS logs
- Collecting diagnostic information
should be implemented once as scripts or standard commands and then called by the agent.
These scripts should be provided as reusable skills with a clearly defined interface, documented inputs, and predictable outputs.
The agent then simply needs to select and call the appropriate skill, rather than repeatedly generating commands through trial and error.
Anthropic’s skill for testing web applications demonstrates this pattern: bundled helper scripts are treated as black boxes and called directly. This eliminates the need to unnecessarily load their source code into the context, while simultaneously providing a reproducible way to manage servers and run tests.
Unit and Integration Tests
They verify that the generated changes meet the expected behavior and prevent regressions before the agent continues working with a faulty result.
Formatters and Linters
They automatically enforce structure and consistency, rather than using model interactions for style corrections.
Security and Policy Scans
They detect secrets, vulnerable dependencies, insecure patterns, and unauthorized changes using clear pass/fail signals.
Operational Scripts
They retrieve logs, start local services, reproduce errors, or collect diagnostic data in a stable, pre-tested format.
These checks should be run locally for quick feedback and then again in CI/CD as a gate that determines whether a change is deployed.
This creates a tight feedback loop:
Agent changes code → deterministic test evaluates the change → agent receives a pass/fail result → next step
A test or scan takes just a few seconds. Skipping it and leaving the agent to guess, on the other hand, often costs more: A wrong approach can trigger several additional corrections, each of which introduces extra logs and diffs into the context.
Practical Rule
The model should be used for evaluation, ambiguity resolution, and adaptation. Scripts, tests, hooks, and CI/CD should handle repeatable execution and enforcement.
If a workflow can provide a unique exit code or a structured result, this signal should be preferred over letting the model decide for itself whether its own work is correct.
5. Keep long conversations concise: Summarize or start over at the right moment
Long discussions build up a kind ofcontext debt: failed approaches, outdated requirements, repeated logs, and assumptions that no longer apply. Claude’s costrecommendations emphasize context management, model selection, Extended Thinking settings, and preprocessing hooks as key levers for reducing consumption.
The /usage view in Claude Code can map current usage to areas such as skills, subagents, plugins, and MCP servers, thereby making context growth more visible.
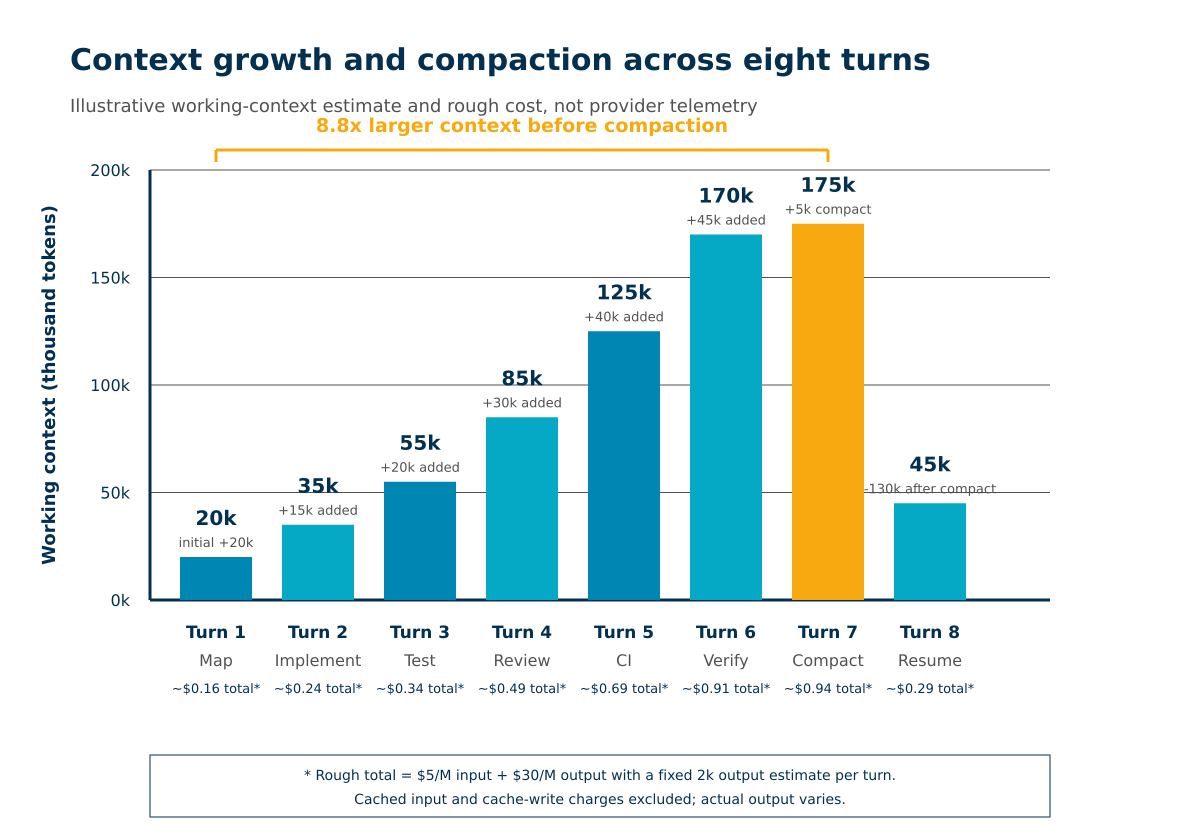
This growth can be illustrated with an example. Here, a “turn” refers to a continuing interaction within the same conversation without compaction¹ or a restart. A truly new conversation would not carry over the entire previous history.
The following figures are illustrative estimates and not telemetry data from a provider. Each estimate represents the complete working context transmitted for that turn—including stored history, instructions, selected files, tool outputs, diffs, and test results.
| Turn | Prompt Example | Work Context | Added | Approximate Cost* | Cumulative Input |
|---|---|---|---|---|---|
| 1 | Map: src/auth/refresh.ts, examine callers and tests; create a plan; make no changes. | 20k | initial +20k | ~$0.16 | 20k |
| 2 | Implement: Update src/auth/refresh.ts, maintain the API and login flow, and add tests for the flow and invalid tokens. | 35k | +15k | ~$0.24 | 55k |
| 3 | Test: Diagnose the error in tests/auth/refresh.test.ts; make a minor correction and run the test again. | 55k | +20k | ~$0.34 | 110k |
| 4 | Review: Check diff, API, callers, error handling, and code coverage; fix only necessary regressions. | 85k | +30k | ~$0.49 | 195k |
| 5 | CI: Reproduce and fix the type error in the branch for invalid tokens; limit the scope to affected files. | 125k | +40k | ~$0.69 | 320k |
| 6 | Verify: Run focus tests, type checks, and lint; report exact results and remaining risks. | 170k | +45k | ~$0.91 | 490k |
| 7 | Compact: Receive goals, decisions, files, test status, risks, and API contracts for the next turn. | 175k | +5k Compact | ~$0.94 | 665k |
| 8 | Summary: Use the reduced handover context, repeat the final review, and report the results and any remaining risks. | 45k | −130k after Compact | ~$0.29 | 710k |
“Added” refers to the initial context for Turn 1, the newly introduced context through Turn 7, and the context reduction shown after compression in Turn 8.The rough cost estimates combine uncached input at $5 per 1 million tokens and a fixed output estimate of 2,000 tokens at $30 per 1 million tokens. Cached input and cache-write costs are excluded.The cumulative input sums the entire working context transferred in each turn, not just the visible prompt. The compressed handover context is intentionally much smaller than the original conversation, so that Turn 8 starts with 45k tokens instead of 175k.
When should you compress or restart?
Summarize the context after a significant milestone, such as after the diagnosis and before implementation.
Start a new conversation if the goal changes.
In doing so, provide a structured handoff that includes:
- Objective and scope
- Decisions already made
- relevant files and symbols
- Current test status
- Remaining tasks and risks
When compressing the file, a brief note should also be included specifying which information must be retained in the summary.
For example, prioritize:
/compact Focus on code samples and API usage
these details over a general summary.
The instruction should be tailored to the specific task—for example, with a focus on:
- architectural decisions
- failed test outputs
- modified files
- Unresolved risks
- Exact API contracts
Custom compaction instructions make the reduced context more useful and reduce the likelihood that missing information will need to be re-researched later.
Compaction only works after a session has built up sufficient conversation history. Otherwise, in a new session, Claude returns the following error:
“Not enough messages to compact.”
6. Preserving the prompt cache during a coding session
Prompt caching allows an AI model to reuse parts of a context that has already been processed. This can include system instructions, file contents, conversation history, and tool definitions.
This is particularly valuable in agent-based coding workflows, where the same extensive context is repeatedly passed back and forth over many turns.
According to GitHub, cached tokens are typically charged at about 10% of the normal input token price. The exact price depends on the specific model.
It’s crucial to understand how the cache determines what can be reused.
The ClaudeCode Guide describes the mechanism as prefix matching: The model reprocesses the entire request on every turn, while the cache matches the beginning—that is, the prefix—of each request against previously processed content.
The match is exact. A change anywhere in the prefix means that everything that follows must be recalculated. There is no caching at the file or segment level.
To take advantage of this, coding assistants typically structure queries so that the most stable content comes first:
- System prompt and tool definitions
- Project context such as AGENTS.md
- ongoing conversation
A change further down therefore keeps everything before it cached.
A change at the conversation level leaves the previous levels cached, while a change to the system prompt or toolset invalidates everything that follows.
In a normal turn, the cached prefix is essentially the entire previous request; only the last exchange is new. It is precisely this assumption that is used in the following estimate.
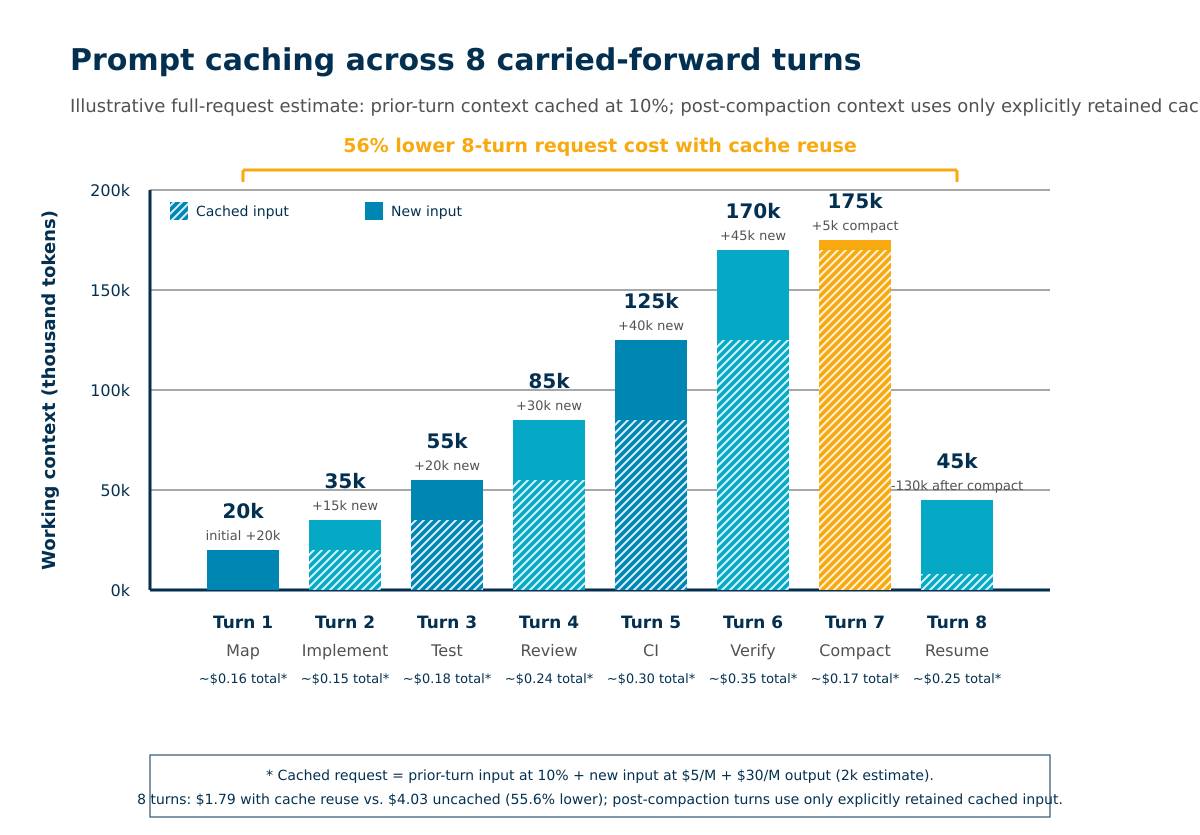
| Turn | Working Context | Cached Input | New Input | Cache Read Cost* | Request with cache* | Without Cache* | Savings |
|---|---|---|---|---|---|---|---|
| 1 | 20k | – | 20k | – | ~$0.16 | ~$0.16 | – |
| 2 | 35k | 20k | 15k | ~$0.01 | ~$0.15 | ~$0.24 | ~$0.09 (38%) |
| 3 | 55k | 35k | 20k | ~$0.02 | ~$0.18 | ~$0.34 | ~$0.16 (47%) |
| 4 | 85k | 55k | 30k | ~$0.03 | ~$0.24 | ~$0.49 | ~$0.25 (51%) |
| 5 | 125k | 85k | 40k | ~$0.04 | ~$0.30 | ~$0.69 | ~$0.38 (56%) |
| 6 | 170k | 125k | 45k | ~$0.06 | ~$0.35 | ~$0.91 | ~$0.56 (62%) |
| 7 | 175k | 170k | 5k | ~$0.09 | ~$0.17 | ~$0.94 | ~$0.77 (82%) |
| 8 | 45k | 8k | 37k | ~$0.004 | ~$0.25 | ~$0.29 | ~$0.00 (0%) |
| Total | – | – | – | ~$0.25 | ~$1.79 | ~$4.03 | ~$2.24 (56%) |
Under these assumptions, caching reduces the estimate for the eight turns from approximately $4.03 to $1.79. This corresponds to a savings of $2.24, or 56%. The savings per turn increase from about 38% in Turn 2 to 82% in Turn 7 because the cached portion grows from 20,000 to 170,000 tokens, while only the newly added input is calculated at the full input price. Turn 8 still benefits slightly from the cache after compression: 8,000 tokens from the compressed handoff remain cached. This reduces the estimated price from $0.29 to $0.25. However, caching does not make the entire request 90% cheaper. Output, new input, and context after compression still incur costs. Repeated context simply becomes significantly cheaper as long as the cache remains valid.
How is the cache maintained?
To benefit from caching, the session configuration should remain stable.
Before starting the task, determine the following:
- Model
- Reasoning Level
- Context size
- Enabled tools
and do not change these settings during a single, continuous task.
The Claude Code Guide summarizes this principle as follows:
Select the model and reasoning level at the start of the session and reserve compaction for natural transitions between tasks.
The fewer changes made during a task, the higher the cache hit rate.
These actions clear the cache
Switch models:
A model cannot reuse another model's cache. The model is part of the cache key.
Changing reasoning or tool settings:
A change to the reasoning level or context size causes the entire query to be recalculated. Adding, removing, connecting, or disconnecting tools, MCP servers, or plugins can also change the system prompt and thus invalidate the prefix cache.
Updating the wizard during a session:
A new version typically changes the system prompt or tool definitions. The next turn may therefore need to completely rebuild the cache.
These actions, on the other hand, keep the cache warm
Several common actions can be cached because they are simply appended to the end of the conversation:
- Invoking skills and commands
- Generating a terminal summary
- Changing the permission mode
- Editing repository files
If you want to exit a dead-end path, it’s better to jump back to an earlier turn than to perform compaction. Jumping back cuts the conversation back to an already cached prefix, while compaction creates a new prefix.
Time also plays a role
Cached prefixes expire after a certain period of inactivity.
GitHub states that caches expire after 24 hours of inactivity for OpenAI models and after one hour for most other models.
The Claude Code Guide specifies five minutes by default, which can be automatically extended to one hour with a Claude subscription.
After a longer pause, the first turn may need to process the entire history again without using the cache. In this case, it makes more sense to start a new session or run /compact so that the context is rebuilt from a compact summary rather than from the full conversation history.
Finally, you should verify that caching is actually working.
Coding assistants typically display:
- Cache-Read-Token
- Cache-Write-Token
A high read-to-write ratio indicates a stable prefix. If, on the other hand, the write values remain high turn after turn, something is likely changing in the prefix.
7. AGENTS.md: Keep it short, curated, and accountable to people
Persistent instruction files and tool definitions consume context before the assistant begins the actual task. AGENTS.md and CLAUDE.md are essentially the same artifact: an instruction file that the assistant automatically loads, regardless of whether it is stored at the user, organization, repository, or subdirectory level. AGENTS.md is the tool-agnostic convention adopted by many assistants, while Claude Code reads a file named CLAUDE.md; throughout the rest of this section, AGENTS.md will be used to represent any such file. These files are valuable when they document non-obvious coding conventions, mandatory rules, architectural constraints, and quality requirements. However, any globally loaded directive competes with the code and information needed for the current decision. The file is automatically loaded at the start of each session, so any detailed procedure it contains remains in the base context even for tasks where that procedure is irrelevant.
Do not automatically generate AGENTS.md, and do not simply adopt the result as a repository guideline. Gloaguen et al. found that repository context files generated by LLMs did not improve task performance and that context files increased inference costs by more than 20% on average. The agents generally followed the added instructions, but the additional requirements led to more extensive file exploration, additional tests, and more tool calls; repository overviews, in particular, proved to be of little help. Automatically generated instructions can therefore add context that seems plausible but makes routine tasks more expensive or difficult without contributing information that the agent could not have determined on its own.
Instead, treat the file as a small, human-maintained configuration artifact. Maintainers should add only minimal, verified requirements that are both non-standard and generally applicable. These include, for example, mandatory build and test commands, unusual package manager choices, architectural constraints that must not be violated, and mandatory validation or security rules. Omit generated directory trees, repository summaries, recognizable technology descriptions, duplicate README content, and style rules that are already enforced by formatters or linters. Review every proposed line in a pull request, assess whether it improves representative tasks, and remove directives that demonstrably have no impact on correct behavior. Limit permanently loaded directive files to guidelines that apply broadly and consistently. Move task-specific procedures—such as pull request reviews, release processes, database migrations, or incident response—into skills that are loaded only when relevant. For example, replace a 100-line migration procedure in AGENTS.md with a dedicated database migration skill that can be invoked as needed.
Apply the same principle to tools. Large tool collections—such as a full MCP server with numerous available operations—add tool descriptions to the context with every request. Therefore, as far as the workflow allows, activate only the MCP servers, plugins, and tool sets required for the current task. A focused tool configuration reduces the base context, limits the wizard’s options, and minimizes the risk of irrelevant tool calls.
Both measures follow the same principle of gradual disclosure: Keep the persistently active base small and make detailed procedures and tool definitions available only when a task requires them.
A practical rule of thumb is: Keep AGENTS.md under about 200 lines and review the persistent context as you would production code. Remove duplicate statements, obsolete exceptions, unused tools, and text that does not affect behavior. Before starting a task, ask yourself two questions: “Does the assistant need to know this for every request?” and “Does this tool need to be available for this task?” If not, load it as needed or leave it disabled.
8. Use English as the default language
Natural language text is converted into tokens before it is processed by a model, and equivalent statements do not necessarily require the same number of tokens in every language. Since many model tokenizers and training corpora are heavily optimized for English, English represents commonly used words and technical terms more concisely than languages such as German or Japanese. For coding assistants, this makes English a sensible default language for persistent instructions that are sent repeatedly—especially for AGENTS.md, skill files, repository conventions, and reusable prompt templates.
The potential savings can be illustrated using the same Git command translated into four languages. Measured using the OpenAI tokenizer for GPT-5.x and O-Series models, the same instruction expands to about 76% more tokens in German and more than twice as many tokens in Japanese compared to the English source, as shown in the following table. The exact ratios depend on the model and tokenizer, but consistent differences are significant when the same instruction files are included in every query.
Example prompt used for the comparison: “Check my current Git branch, identify all commits that haven’t been merged into main yet, suggest an optimal interactive rebase strategy to create a clean commit history, and generate the exact Git commands required to do so.”
| Language | Token count | Additional Tokens vs. English | Relative token usage |
| English | 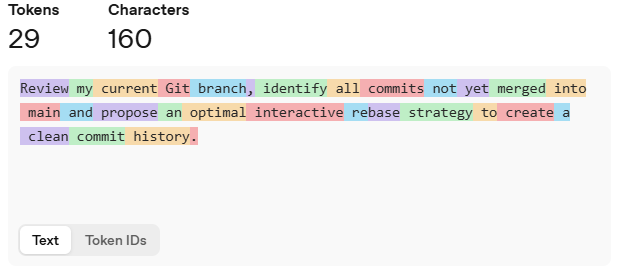 | Baseline | 1.00× |
| Chinese | 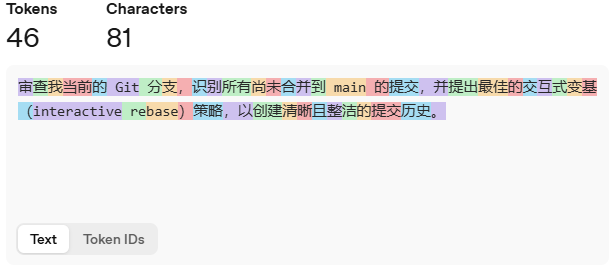 | +17 (+59%) | 1.59× |
| German | 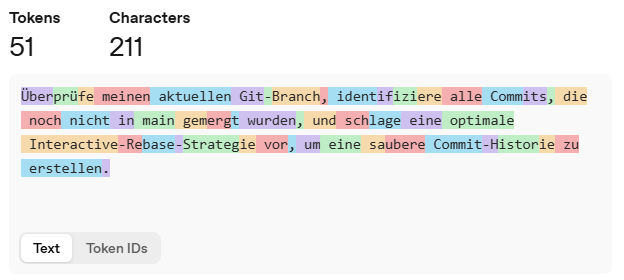 | +22 (+76%) | 1.76× |
| Japanese |
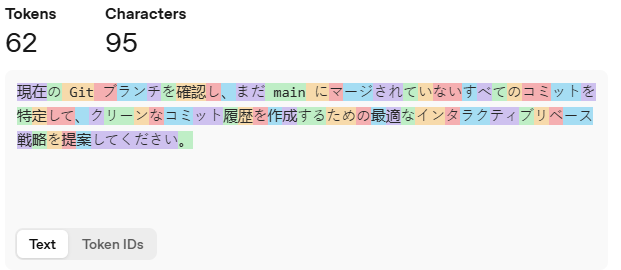
| +33 (+114%) | 2.14× |
Illustrative tokenizer check: counts were measured for the translated prompt shown above using the OpenAI tokenizer setting for GPT-5.x and O-series models.
In practice, reusable technical instructions should be standardized in English if the team can reliably review them. However, English should not be enforced in every interaction. The context of a coding assistant often consists of source code, diffs, tool definitions, and command outputs, so a one-time prompt may account for only a small portion of the total cost. A clear, precise prompt in the developer’s strongest language is preferable to a vague or error-prone English prompt that causes additional searches, corrections, or failed attempts.
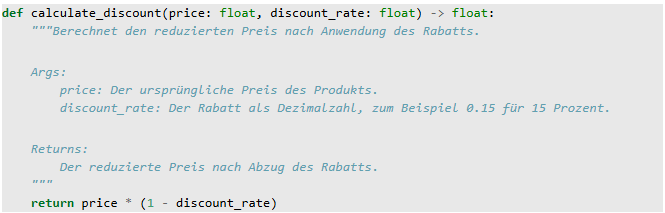
The same principle applies directly within source files. Docstrings, comments, and inline explanations are frequently re-read by coding assistants when they examine functions, generate summaries, create tests, or edit the same file again after a failed attempt. A German docstring may be perfectly understandable to a German-speaking team, but it can create avoidable token overhead and make the surrounding technical context less consistent for the assistant.
Avoid this pattern in shared repository code:
Prefer the English version:
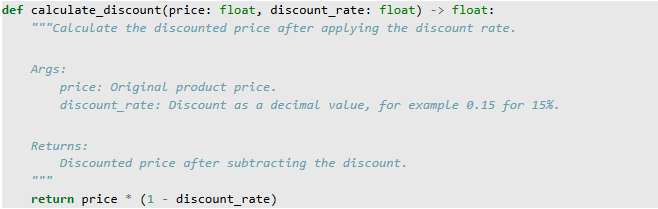
This may seem harmless at first, but it becomes costly when the same file is loaded repeatedly during an agent-driven workflow. The assistant may read this function while planning a change, re-examine it while editing related tests, revisit it after a failed test run, and include it later in summaries or diffs. Each repetition resends the non-English natural-language explanation and expands the context without adding any additional information that couldn’t be expressed more concisely and consistently in English.
English docstrings also create a more consistent common ground for mixed teams, open-source conventions, external libraries, and coding assistants that have been extensively trained on English technical material. The recommendation is not to prohibit communication in local languages, but to keep reusable technical context—docstrings, comments, repository instructions, examples, and prompt templates—in English if these files are likely to be processed repeatedly by AI tools.
This recommendation is a guideline, not a hard-and-fast rule, and there are good reasons to deviate from it. The underlying goal is a consistent language for the repeatedly used technical context within a repository or session—English is simply the most token-efficient choice for most tokenizers and is not an end in itself. If there is a stronger reason to use a different language, that reason should be followed: a team with limited English proficiency will write and review better code in its own language; Software intended for a specific market may require identifiers and documentation in the local language; and some clients or regulated sectors explicitly require that code and docstrings be written in a specific language. In these cases, the benefits for clarity and accuracy outweigh the moderate token overhead. What rarely makes sense is a third language that no one on the team masters well—configuring the test harness, instructions, and prompts in a language you are not fluent in, even though English would be more suitable, incurs additional costs without corresponding benefits.
9. Don't use C++ and JSON—at least not solely for token efficiency
The headline is intentionally tongue-in-cheek: No one should rewrite a suitable C++ system just to save on prompt tokens. The choice of a programming language must continue to be determined by runtime requirements, the ecosystem, security, maintainability, team expertise, and compatibility. Nevertheless, programming languages all represent the same logic using different amounts of syntax, boilerplate, and type information. Therefore, a repository’s primary language can influence how much source code fits into an agent’s context window. Martin Alderson’s exploratory comparison of comparable Rosetta Code solutions revealed significant differences between programming languages, with concise dynamic and functional languages generally using fewer tokens than more verbose low-level languages. The analysis is useful as an indicator, not as a benchmark for selecting a programming language: The author explicitly points out limitations and biases in the dataset, and the number of tokens, on its own, says nothing about correctness, performance, security, the quality of the generated code, or the number of iterations an agent requires. When selecting a new technology, consider language efficiency as a secondary factor—not as a reason to abandon an established C++ codebase.
The following table shows the Token Calculator’s ranking based on the average number of tokens for Rosetta-style tasks; the original rating column has been omitted.
| Language | Ø Tokens (Rosetta task) | Type System |
|---|---|---|
| J | ~70 | Dynamic |
| Clojure | ~109 | Dynamic |
| Ruby | ~119 | Dynamic |
| Python | ~128 | Dynamic |
| Haskell | ~130 | Static |
| F# | ~136 | Static |
| Lisp | ~145 | Dynamic |
| Scala | ~166 | Static |
| JavaScript | ~177 | Dynamic |
| Go | ~182 | Static |
| C# | ~216 | Static |
| Java | ~224 | Static |
| C++ | ~250 | Static |
| C | ~283 | Static |
Source: Token Calculator, “Most Token-Efficient Languages for LLMs, Ranked & Priced,” based on Rosetta-style programming tasks and measurements using tokenizers. The original rating column has been omitted here.
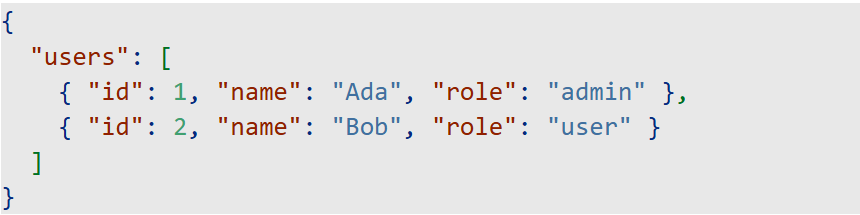
Token efficiency is also not the same as overall efficiency. A language or representation that is compact for an LLM may still be inefficient once the generated or maintained code is executed. Specifically for AI workloads, Marini et al. show that the choice of programming language can significantly impact energy consumption: In their controlled GREENS-2025 experiment using C++, Java, Python, MATLAB, and R, compiled and semi-compiled languages generally consumed less energy than interpreted languages, which in some cases required up to 54 times more energy. They also emphasize that the most energy-efficient choice depends on the algorithm, the training or inference phase, the implementation, and development trade-offs. Therefore, decisions regarding language and format for AI-powered software should jointly consider token costs, maintainability, ecosystem suitability, runtime performance, and energy efficiency. For structured data sent to a model, the format is easier to change. Token-Oriented Object Notation (TOON) is a lossless representation of the JSON data model designed for LLM inputs. It replaces repeated keys, curly braces, and quotation marks with indentation and tabular rows. Its strongest use case is a uniform array of objects; deeply nested or irregular data may be better suited to JSON. Therefore, representative payloads should be evaluated before implementation.
Example payload in JSON:
Corresponding Payload in TOON:
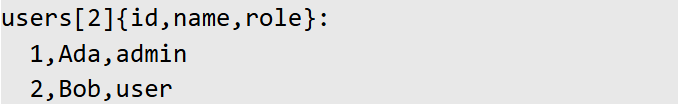
In this TOON encoding, the header users[2]{id,name,role} declares the array once: [2] specifies the number of lines that follow, and {id,name,role} lists the fields shared by each user. Each user is then reduced to a single comma-separated line, rather than repeating the keys, curly braces, and quotation marks. The TOON documentation reports that for this type of sample data, there are about 117 tokens in JSON compared to about 66 in TOON. However, the savings depend on data structure, formatting, and the tokenizer.
As compact as this may seem, stick with JSON as the standard and treat TOON as a strictly limited exception. JSON is universally supported, dominates model training data, and can be easily examined and filtered using standard tools like jq. Use TOON for large, uniform arrays where representative benchmarks show actual token savings without a loss of accuracy—and use it only at the LLM boundary, not as a canonical application or API format.
For coding agents, this is the norm rather than the exception: they operate in long sessions with many interactions. A benchmark study on token-optimized formats in agent-based systems found that TOON reduced the number of tokens by up to 18%, but with a loss in accuracy of approximately 9 percentage points. Furthermore, “TOON loses even more accuracy in multi-turn scenarios, where parsing errors lead to additional reasoning iterations and offset the savings per call” (Kutschka & Geiger, 2026). The study concludes that TOON “cannot be considered a standard.” The same study rated TRON (Token Reduced Object Notation) as safer—with up to 27% fewer tokens while maintaining accuracy within 14 points of JSON—when the workload contains many structurally similar tool schemas. Measure the total cost and task quality for your own workload before deploying either format.
10. Use dedicated tools to carefully optimize token usage
Even well-defined coding tasks can generate a significant amount of context: test results, compiler output, repository scans, logs, structured payloads, tool responses, and previous messages. A growing ecosystem of tools promises to reduce this overhead by compressing, filtering, or restructuring the information that reaches the model. Examples include RTK, Headroom, Context Mode, Caveman, Ponytail, repository graph tools, symbol indexes, and compact data formats.
These tools can be useful but should not be viewed as a universal solution for cost savings. Advertised savings of 33–99% per compressed payload may be technically feasible, while the impact on the overall bill remains minimal. In full Coding Agent sessions, many tokens fall outside the compressible range: repository context, tool definitions, prompt cache read and write operations, conversation history, reasoning overhead, generated code, and file diffs.
As a result, the effects of compression are often diminished over time. In a short, output-heavy session, a tool that removes verbose logs or conversation filler can save a noticeable proportion of tokens. In a long coding session, however, these savings can be offset by repeated retrievals, cache activity, accumulated history, and non-compressible code or tool traffic. A useful independent data point comes from an analysis of approximately 500 Claude code sessions with 614 million tokens processed and a base cost of about $926. Although some tools had advertised significant savings per payload, the measured impact on actual total costs was moderate: Headroom saved 2.8%, RTK 0.5%, Caveman 0.4%, and all tools combined 3.7%. The conclusion is not that these tools are useless, but rather that high advertised compression rates rarely translate directly into correspondingly high savings in total costs.
| Tool | Advertised Benefit | Observed Total Cost Reduction | Source |
|---|---|---|---|
| Headroom | Significant reduction in context | 2.8% | CodePointer RTK Study |
| RTK | 60–90% reduction in output tokens | 0.5% | CodePointer RTK study |
| RTK | 60–90% reduction in output tokens | +7.6% cost with low reasoning effort; no measurable savings with high reasoning effort | JetBrains RTK Benchmark |
| Caveman | 65% reduction in output tokens | 0.4% | CodePointer RTK Study |
| Caveman | 65% reduction in output tokens | 8.5% reduction in output tokens for realistic Claude code tasks | JetBrains Caveman Benchmark |
| Ponytail | Less generated code and simpler implementations | 10.3% | JetBrains Ponytail Benchmark |
Recent JetBrains benchmarks tell the same story in a controlled environment. Caveman advertised a 65% reduction in output tokens, but actual savings measured on realistic Claude Code Agent tasks were 8.5%. A separate JetBrains RTK benchmark found that the 60–90% token reduction advertised by RTK did not result in lower total agent costs: For real-world Claude code agent tasks, RTK was 7.6% more expensive with low reasoning effort and showed no measurable difference in cost with high reasoning effort, while task quality remained unchanged. Ponytail showed more promise because it attempts to reduce unnecessary code generation on its own: JetBrains measured about 15% less code, 10.3% lower costs, and 11% less time—still well below the advertised figures. These results are task-specific and depend on the benchmark harness, model, repository, and the assistant’s architecture.
| Approach | Tools | Best Fit | Rating |
|---|---|---|---|
| Repository Graph and Structural Retrieval | CodeGraph, Graphify, codebase-memory-mcp | Large repositories and repeated exploration | Often useful, as they prevent irrelevant context from being loaded in the first place. Validate retrieval quality, index freshness, language support, and details regarding local processing. |
| Output Filtering and Compression | RTK, Context Mode, Headroom | Output-heavy workflows with detailed logs, shell commands, or repeated tool results | The savings at the session level may be significantly lower than advertised. In the JetBrains RTK benchmark, the tool claimed a token reduction of 60–90%, but measurements showed a +7.6% cost increase with low reasoning effort and no measurable savings with high effort. Ensure that the filters retain errors, stack traces, warnings, order, security results, and other diagnostic information. |
| Repository Packaging | Repomix | One-time reviews or wizards without native repository access | Useful for portability, but not automatically token-efficient. Packaging an entire repository can still generate a large prompt. |
| Communication Compression | Caveman | Conversation- or explanation-heavy agent workflows | Actual savings exist, but JetBrains measured an 8.5% reduction in output tokens compared to the advertised 65% on realistic Claude code tasks. This does not reduce code, diffs, tool calls, or input context. |
| Code minimization | Ponytail | Agents that tend toward over-engineering or unnecessary custom code generation | Promising, because it not only compresses text but also reduces the generated code. JetBrains measured approximately 10.3% lower costs and 11% less time. However, the results depend on whether the task allows for a simpler implementation. |
Security and governance deserve special attention. Tools like RTK intercept or modify command outputs before they are presented to the model. This can remove noise, but it can also result in the loss of information. Overly aggressive filtering can hide warnings, stack traces, failed checks, policy violations, secret detection results, or other security-related signals. In regulated or security-sensitive environments, teams should retain raw logs for traceability, test filters using representative errors, and avoid compressing output from security or compliance checks unless the original details remain available.
These investigations are also specific to their respective harnesses and the architecture of the assistant. Claude Code, GitHub Copilot, Cursor, Aider, OpenCode, and other coding assistants differ in how they manage context, tools, caching, repository access, and agent loops. A tool that is helpful in one environment may have less impact, no impact, or pose different risks in another. Therefore, teams should benchmark these tools against their own repositories, task distribution, security requirements, and quality gates before deploying them extensively.
The practical recommendation, therefore, is to proceed with caution: Use these tools selectively for short, output-intensive sessions or clearly identified bottlenecks—not as a substitute for good task scoping, selective retrieval, deterministic workflows, and clean session management. The most reliable strategy remains to prevent irrelevant context from entering the session in the first place.
Conclusion
Working efficiently with AI coding assistants is primarily a matter of context engineering—and this same discipline, which reduces costs, also shortens delivery time, because an agent that receives the smallest possible sufficient context reaches a correct and verifiable result with fewer interaction steps. The greatest benefits are at the top of the list: precisely defining each task, tailoring the model and reasoning effort to the task, and separating planning from execution. Workflow and session hygiene—deterministic checks, timely compression, and a stable prompt cache—reinforce these benefits, while curated instruction files, English standards, language and formatting decisions, and dedicated compression tools serve as secondary levers whose advertised savings should be validated using real-world repositories, languages, and quality requirements.
The complete list of best practices, sorted by leverage:
- Write precise, clearly defined prompts that specify files, symbols, failed tests, and acceptance criteria—no long descriptions.
- Adapt the model and reasoning effort to the task; test a lighter model with high or maximum reasoning effort before switching to a larger model.
- Separate planning and execution: Plan using a reasoning model, and then execute the approved plan in a new session using a more cost-effective model.
- Let deterministic tools (tests, linters, scans, CI) assess correctness, rather than having the model verify its own work.
- Compress the context at milestones and start a new session when the goal changes. Ensure a structured handoff of the goal, decisions, files, test status, and risks.
- Keep the session configuration stable—model, reasoning effort, and tools—so that the prompt cache remains active during a task.
- Keep AGENTS.md concise (~200 lines), under human control, and free of automatically generated filler content.
- Keep repeatedly loaded context in English—AGENTS.md, skills, docstrings, and prompt templates.
- Consider the token efficiency of programming languages and data formats as a secondary factor—for example, use TOON only at the LLM boundary—and validate them against real-world requirements.
- Use dedicated compression and retrieval tools selectively and benchmark them against your own repositories before deploying them extensively.
The most important principle is simple:
Provide the smallest possible context that is sufficient to make the next correct and verifiable decision.
Teams that apply this principle reduce both costs and latency while making agent behavior easier to understand, verify, and control.